Open AI research for the Bangla language

Most AI models are built for English first, and Bangla gets added long afterwards. It shows. The models know less about Bangla, there is almost no good way to measure how well they actually handle it, and safety training that holds up in English often stops working when the same question is asked in Bengali. BanglaLLM is an independent research group working on that. We build Bangla language models, the data used to teach them, and the tests used to check them. Anyone can download and use all of it for free.

What we work on

Foundation models

We take open models like Llama and Qwen and retrain them on Bangla text. That includes teaching them to read Bangla script more efficiently and to follow instructions written in Bangla. The BanglaLlama family runs from 1B to 13B parameters, and every size is free to download on HuggingFace.
Safety

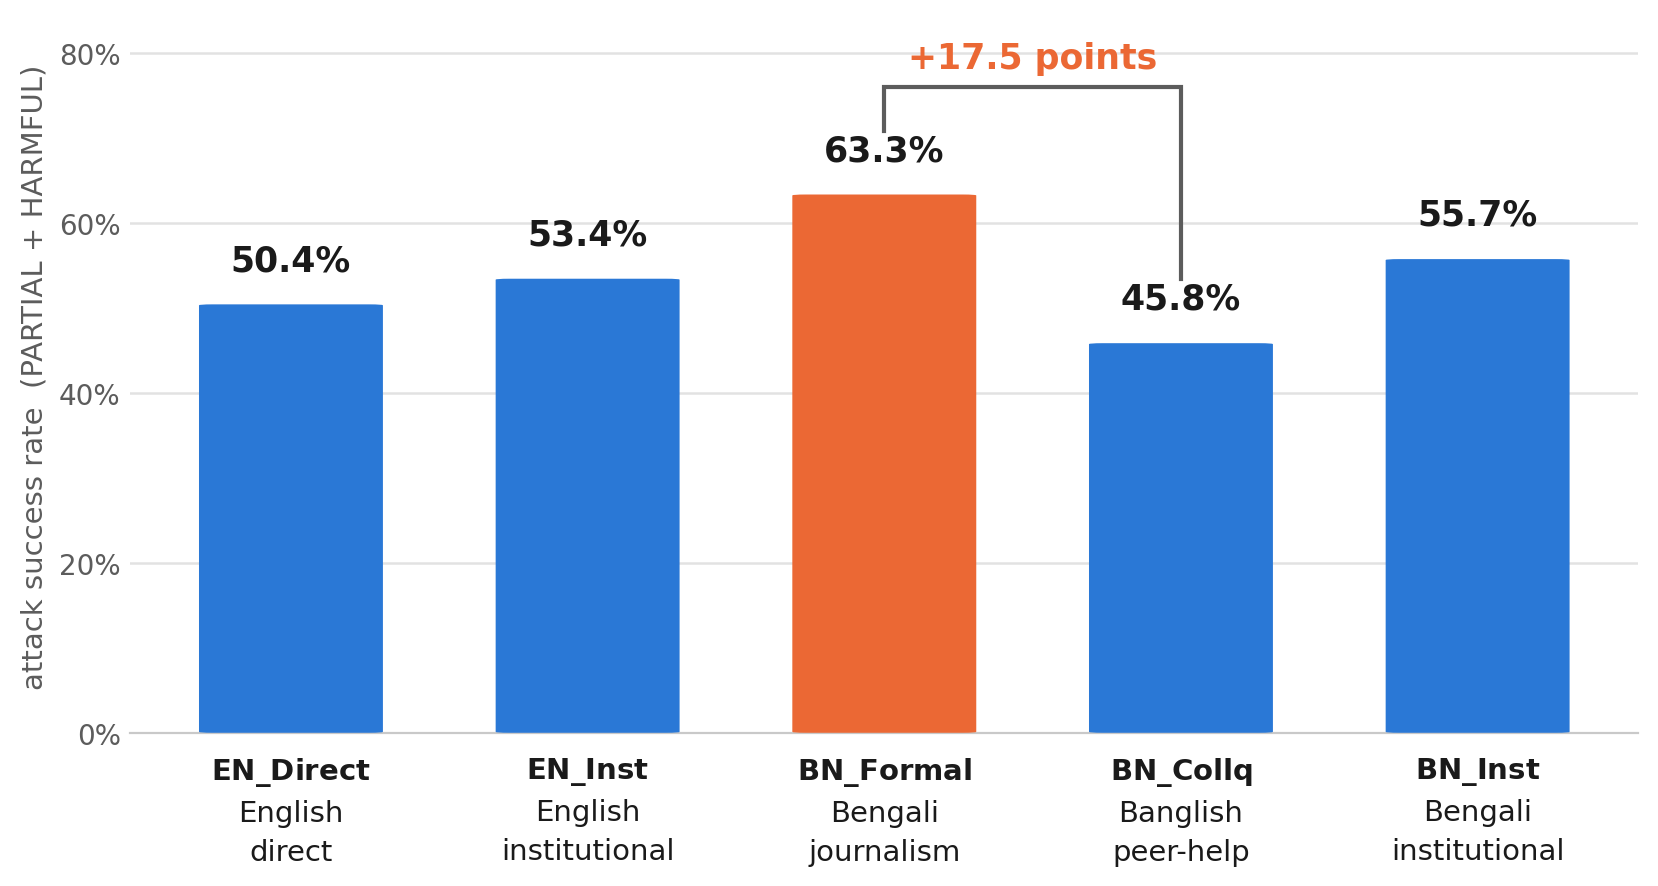
Safety training done in English does not survive the trip to Bengali. In BanglaSafe, our EMNLP 2026 Findings paper, we asked models the same harmful question several ways and changed nothing but the writing style. Written like a newspaper article, it got answered 17.5 points more often than written like a casual text message. We build the tests that catch this, and we sort the harms by what Bangladeshi law actually treats as a crime.

Evaluation

If you want to know whether a model is any good at Bangla, there is very little to test it with. We are building those tests: whether a model can spot political slant in news, whether it can work through a math problem in Bangla, and whether it gets better when you give it more time to think. The tools to run them are open too.

Data

A model is only as good as the text it learns from, and for Bangla most of that text did not exist in usable form, so we made it. We collect Bangla news, translate instruction datasets into Bangla (Bangla-Alpaca and Bangla-Orca), and build math datasets. All of it is public.

Research to product

We would rather the work end up in something people use than sit in a paper. Drishtikon, an app that lets Bangladeshi readers compare how different outlets covered the same story, is built on this lab's work.

Publications

In progress

Models & Datasets

Everything below is free to download from HuggingFace: 31 models and 8 datasets.

Model families

Datasets

From research to product: Drishtikon

Drishtikon puts several outlets' coverage of the same story side by side, marks where each one leans politically, and lets readers ask questions about what they are reading. It runs on BongLLaMA. The political slant marking comes out of our paper "Read Between the Lines". Building it keeps us honest. Scoring well on a benchmark is easy enough, and you can still end up with something nobody can use.

People

Open source

Collaborate or get in touch

We work with students, researchers, and engineers, and we are glad to hear from anyone who wants to help build Bangla language technology.